Published on 7 October 2026
In-Country AI in India: What Businesses Still Need to Secure
Learn what in-country AI inference means and which access, monitoring, retention and human-approval controls Indian businesses still need.
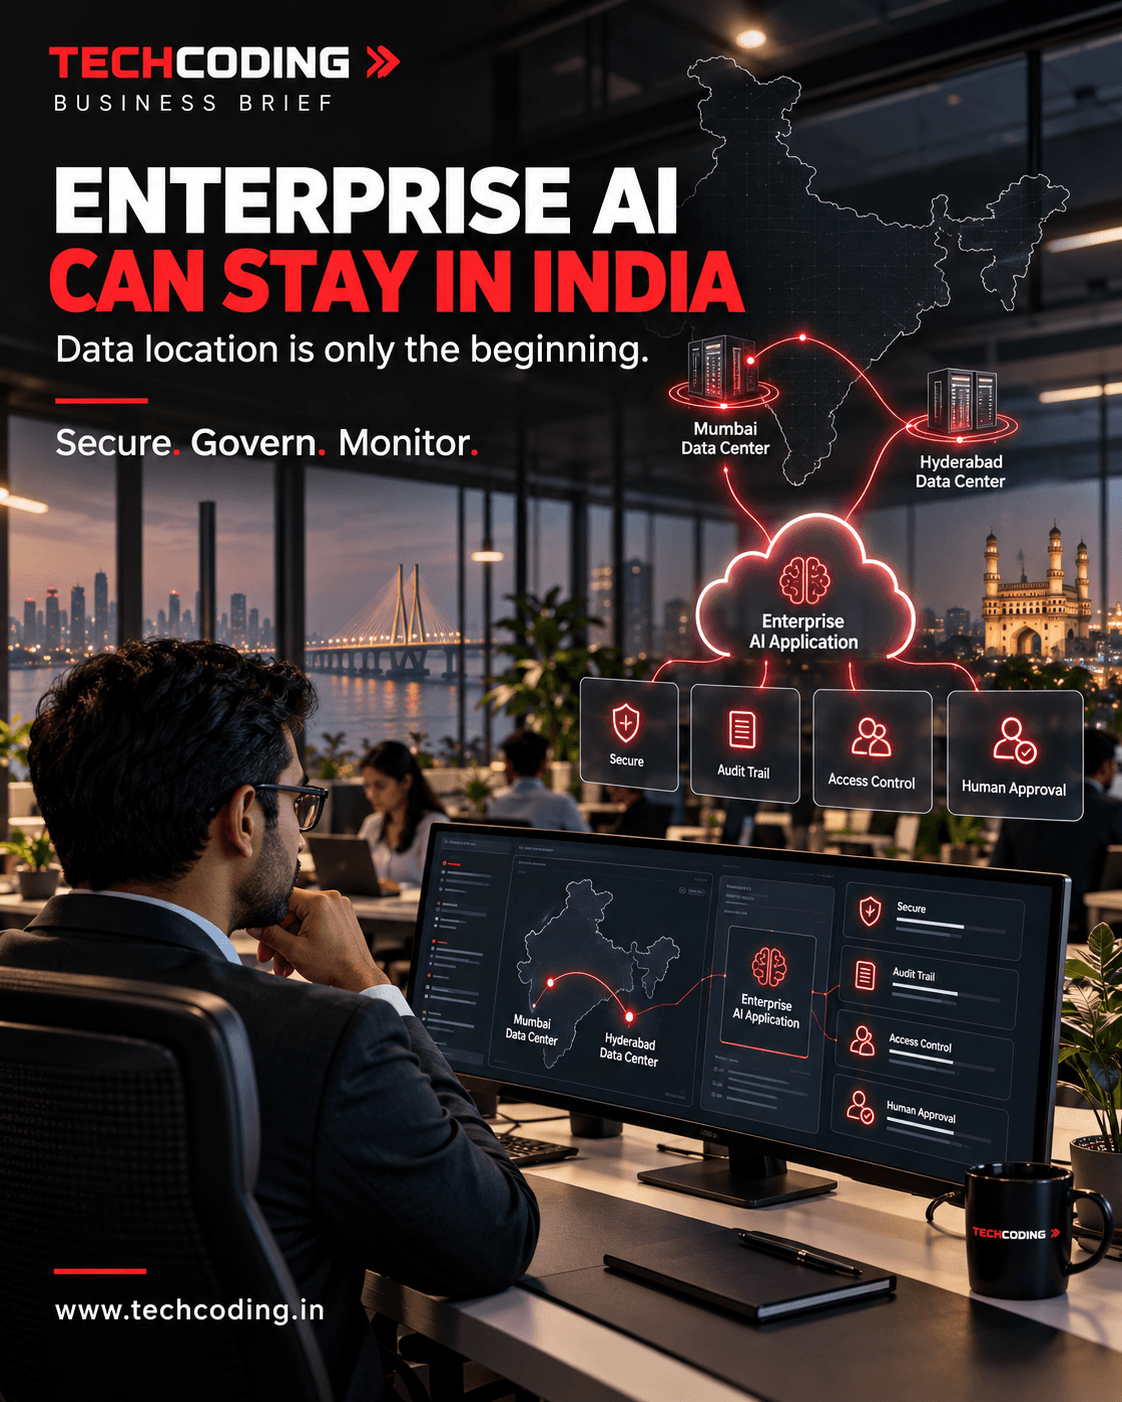
Indian organisations are exploring generative AI for customer service, document analysis, employee assistance, software development and operational automation.
For organisations handling sensitive information, one important question is where prompts and outputs are processed.
AWS has announced India geographic cross-region inference for selected Claude models through Amazon Bedrock. Requests can be routed between the Mumbai region, ap-south-1, and Hyderabad region, ap-south-2, while inference remains within India. Artificial Intelligence
This is an important infrastructure option. It should not, however, be confused with complete compliance.
What in-country inference means
Inference occurs when an application sends instructions and context to a deployed AI model and receives its response.
AWS’s India geographic inference profile can distribute these requests across its two Indian regions. This broader compute pool is intended to improve throughput and resilience during demand peaks.
AWS states that customer data is not stored in the destination region and that Bedrock uses zero data retention by default. Its documentation also identifies model-specific safety-processing considerations that customers should examine before deployment. Artificial Intelligence
Businesses should review the current contractual, technical and regulatory position for their exact application. A marketing statement about data location is not a substitute for this assessment.
Data location is one control—not the whole architecture
Keeping inference inside India does not answer several other questions:
Who can submit sensitive information?
Which data sources can the AI retrieve?
Can the AI update a CRM or approve an application?
Where are prompts, outputs and logs retained?
Which employees can review activity?
What happens if the model provides an incorrect response?
How can access be revoked?
Who approves changes to prompts and connected tools?
These decisions belong in the application architecture and operating process.
Classify data before connecting it to AI
An organisation should define which information may enter the system.
A practical classification could separate:
Public company information
Internal operational information
Customer personal information
Financial or lending information
Authentication credentials and secrets
Highly restricted legal or regulatory records
Each category should have permitted uses, access rules and retention requirements.
For example, a public website assistant may answer using approved service information. An internal NBFC assistant accessing customer documents requires considerably stricter controls.
Apply least-privilege access
AI agents should receive only the permissions needed for their approved task.
A customer-support assistant may need to read a case status but should not necessarily change repayment terms. A document-analysis service may extract values from a bank statement but should not approve a loan.
Important controls include:
Separate service identities
Role-based permissions
Short-lived credentials
Restricted database queries
Approved API endpoints
Action limits
Maker-checker workflows
Emergency access revocation
The system should explicitly deny every action that has not been authorised.
Preserve human control over sensitive decisions
AI can assist with classification, summarisation, drafting and prioritisation. High-impact decisions should retain appropriate human review.
In an NBFC workflow, this could mean:
AI extracts application information.
A rule engine applies approved credit policy.
The system flags anomalies.
An authorised employee reviews exceptions.
Maker-checker approval applies where required.
The platform records the final decision and responsible user.
This provides efficiency without allowing a model response to become an unexplained credit decision.
Monitor inputs, outputs and costs
Production monitoring should cover more than application availability.
Useful measures include:
Requests by user and department
Token consumption and cost
Response latency
Guardrail interventions
Retrieval sources used
Tool or API actions attempted
Failed authentication
Human overrides
Sensitive-data alerts
User feedback and error reports
AWS says usage, performance and costs can be monitored through services including CloudWatch and Cost Explorer. Artificial Intelligence
Application-level monitoring must still be designed around the business workflow.
Plan for failure
AI applications can provide incorrect information, encounter unavailable integrations or exceed capacity limits.
A reliable workflow therefore needs:
Timeouts and retry policies
Approved fallback responses
Human escalation
Duplicate-action protection
Versioned prompts
Model-change testing
Incident logs
Rollback procedures
A failed model request should not leave a customer application or CRM record in an unknown state.
How TechCoding can help
TechCoding helps businesses design controlled AI solutions around existing websites, CRM platforms and operational systems.
This can include:
Enterprise AI application development
Retrieval-augmented generation
CRM and LOS/LMS integration
Role-based access controls
Approval workflows
Prompt and activity logging
Secure API development
Monitoring and cost dashboards
Human escalation processes
The objective is not simply to call an AI model from an application. It is to create a system in which data access, actions and accountability remain understandable.
Visit www.techcoding.in to discuss a governed enterprise AI workflow.